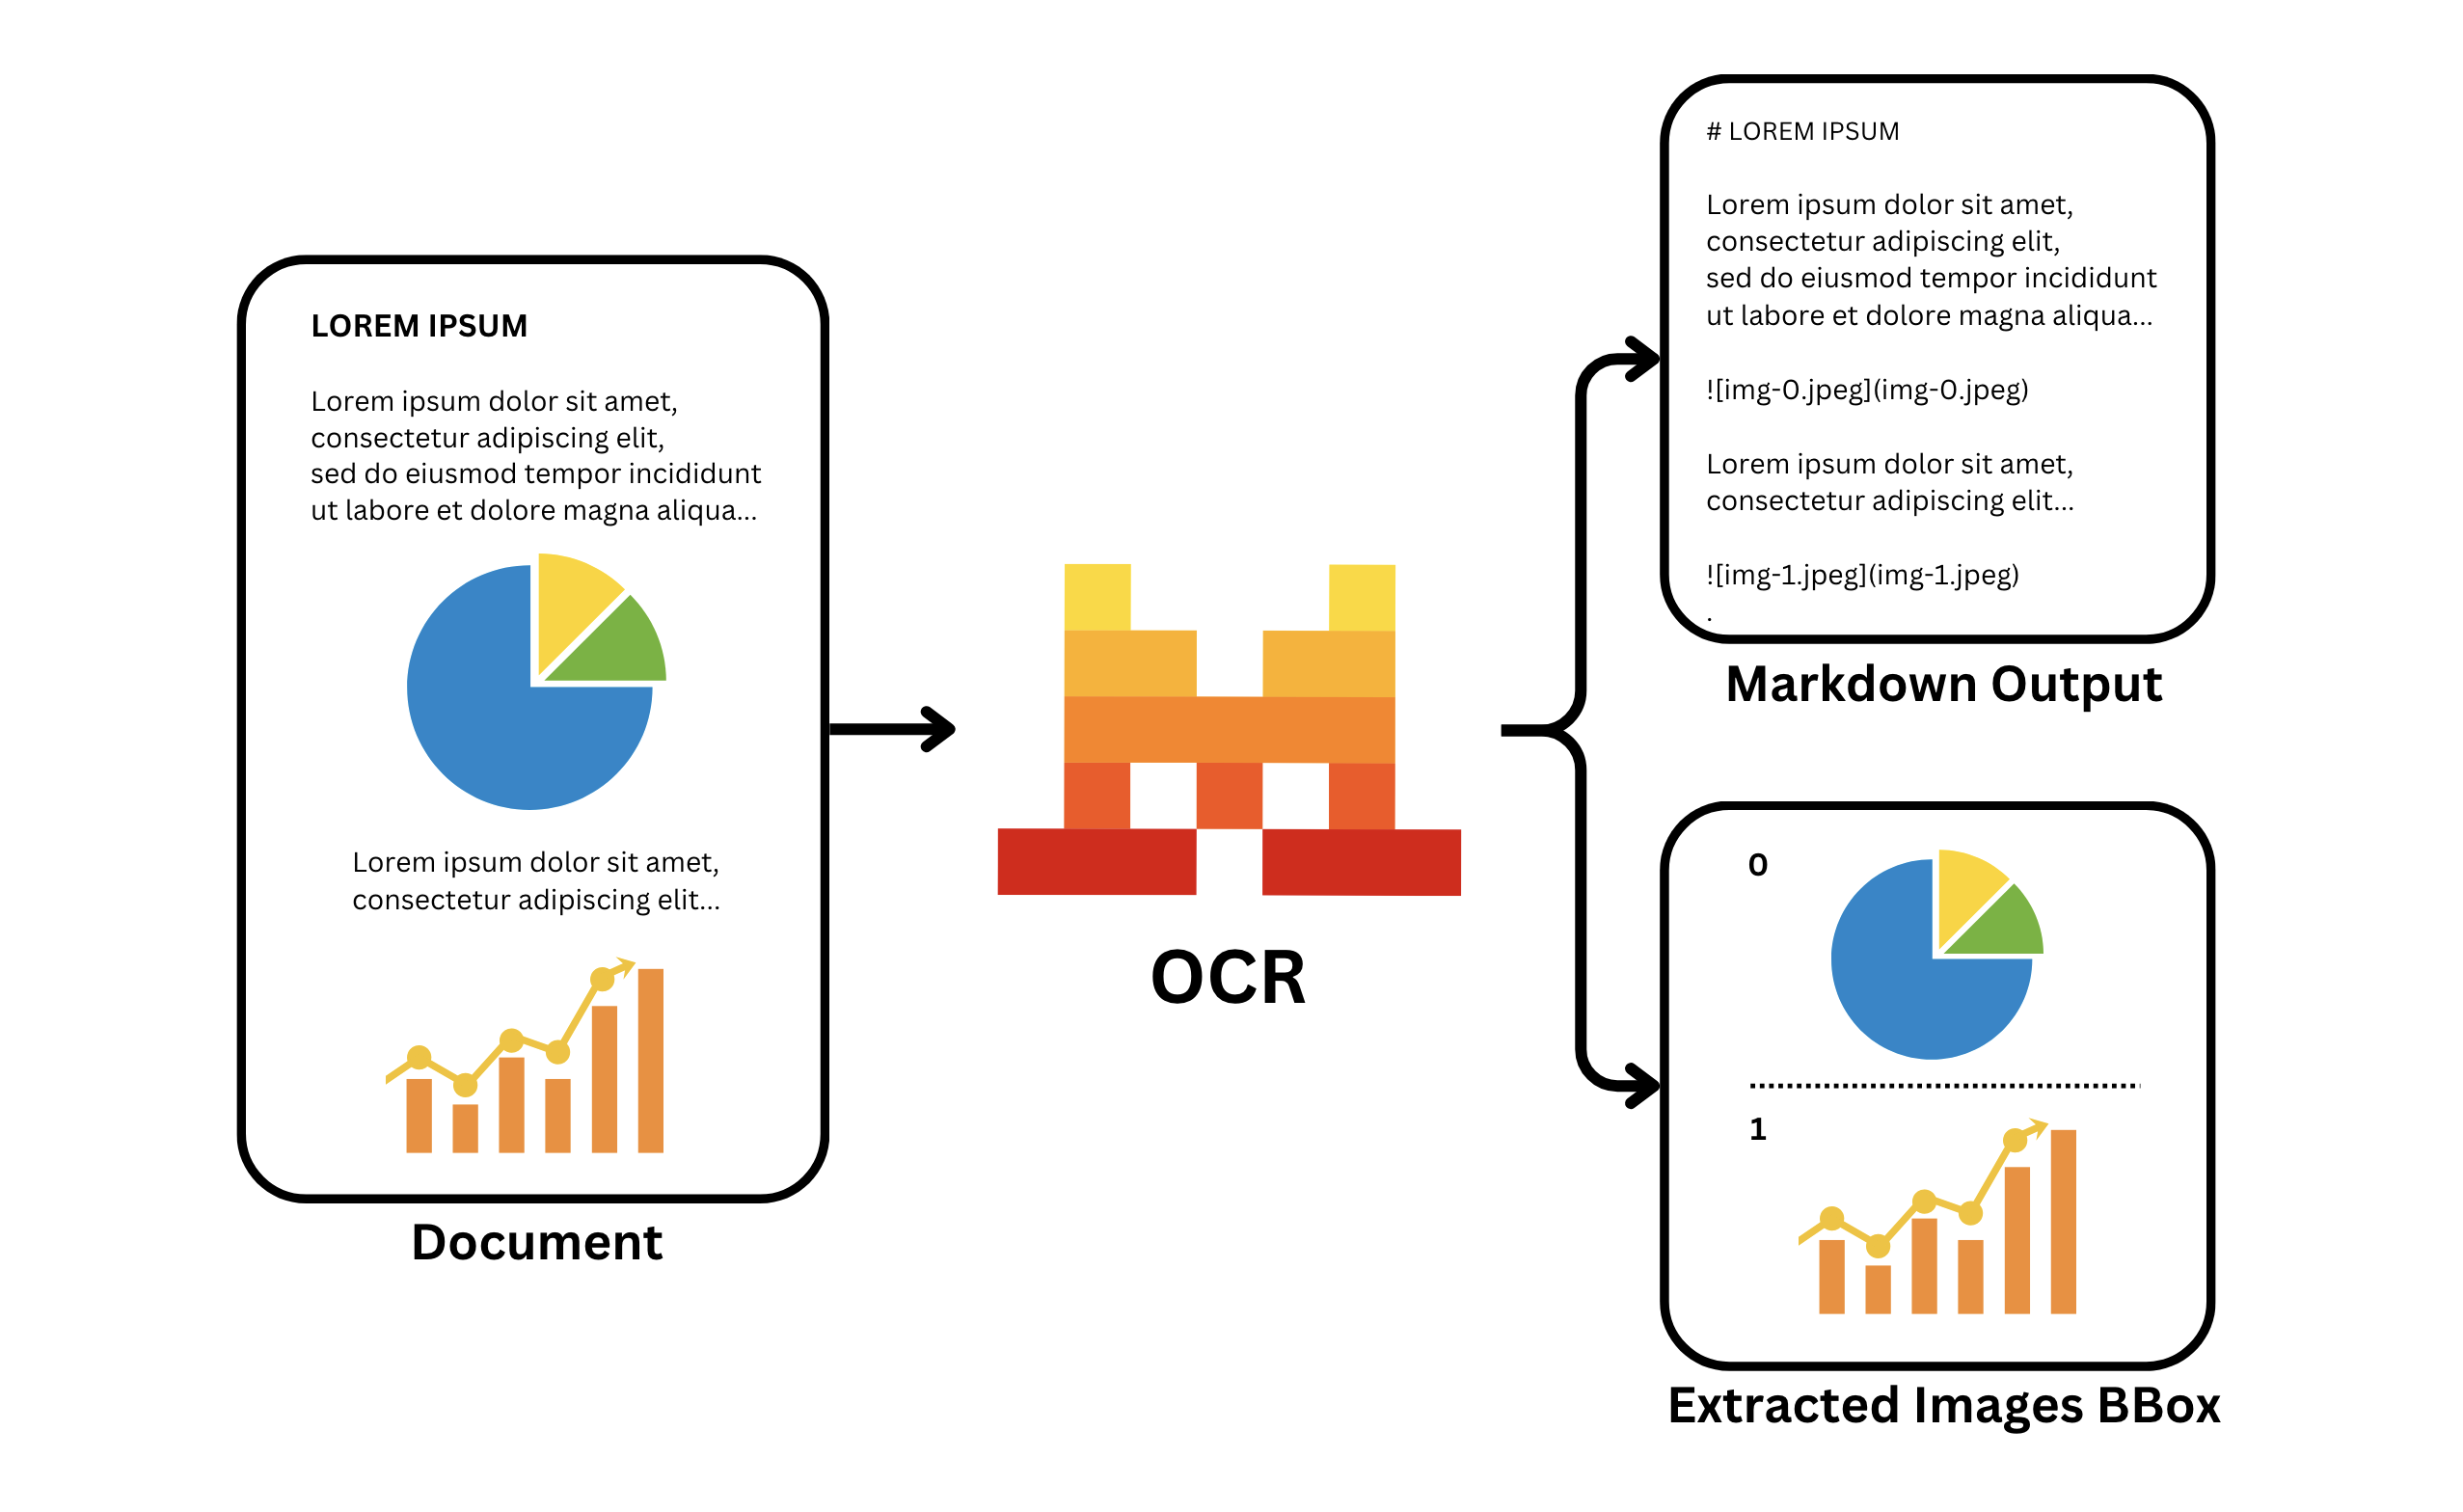
Unstructured documents such as PDFs, scans, or Office files contain valuable knowledge – but Large Language Models (LLMs) struggle to use them directly. To improve answer quality, it’s best to first convert such data into a structured format. Markdown has proven particularly effective, as it preserves document structures (headings, lists, tables, images, formulas, code blocks). This improves LLM understanding, reduces hallucinations, and significantly boosts the performance of Retrieval-Augmented Generation (RAG) pipelines.
Several tools now automate this conversion from unstructured documents into Markdown. The three most relevant solutions are Mistral OCR (cloud service), IBM Docling (open source, local), and MinerU (open source, research context). Below is a comparison of their strengths and weaknesses.
Mistral OCR – Cloud Service with Benchmark Quality
Mistral OCR is an AI-powered document processing service delivered via API.
- Strengths: Outstanding accuracy for complex content (mathematics, tables, images, multilingual text), extremely fast and scalable, no installation required.
- Weaknesses: Cloud-only – documents must be uploaded, pay-per-use pricing, limited self-hosting options.
For companies focused on speed and top-quality results, Mistral is the most powerful solution currently available.
IBM Docling – Open Source
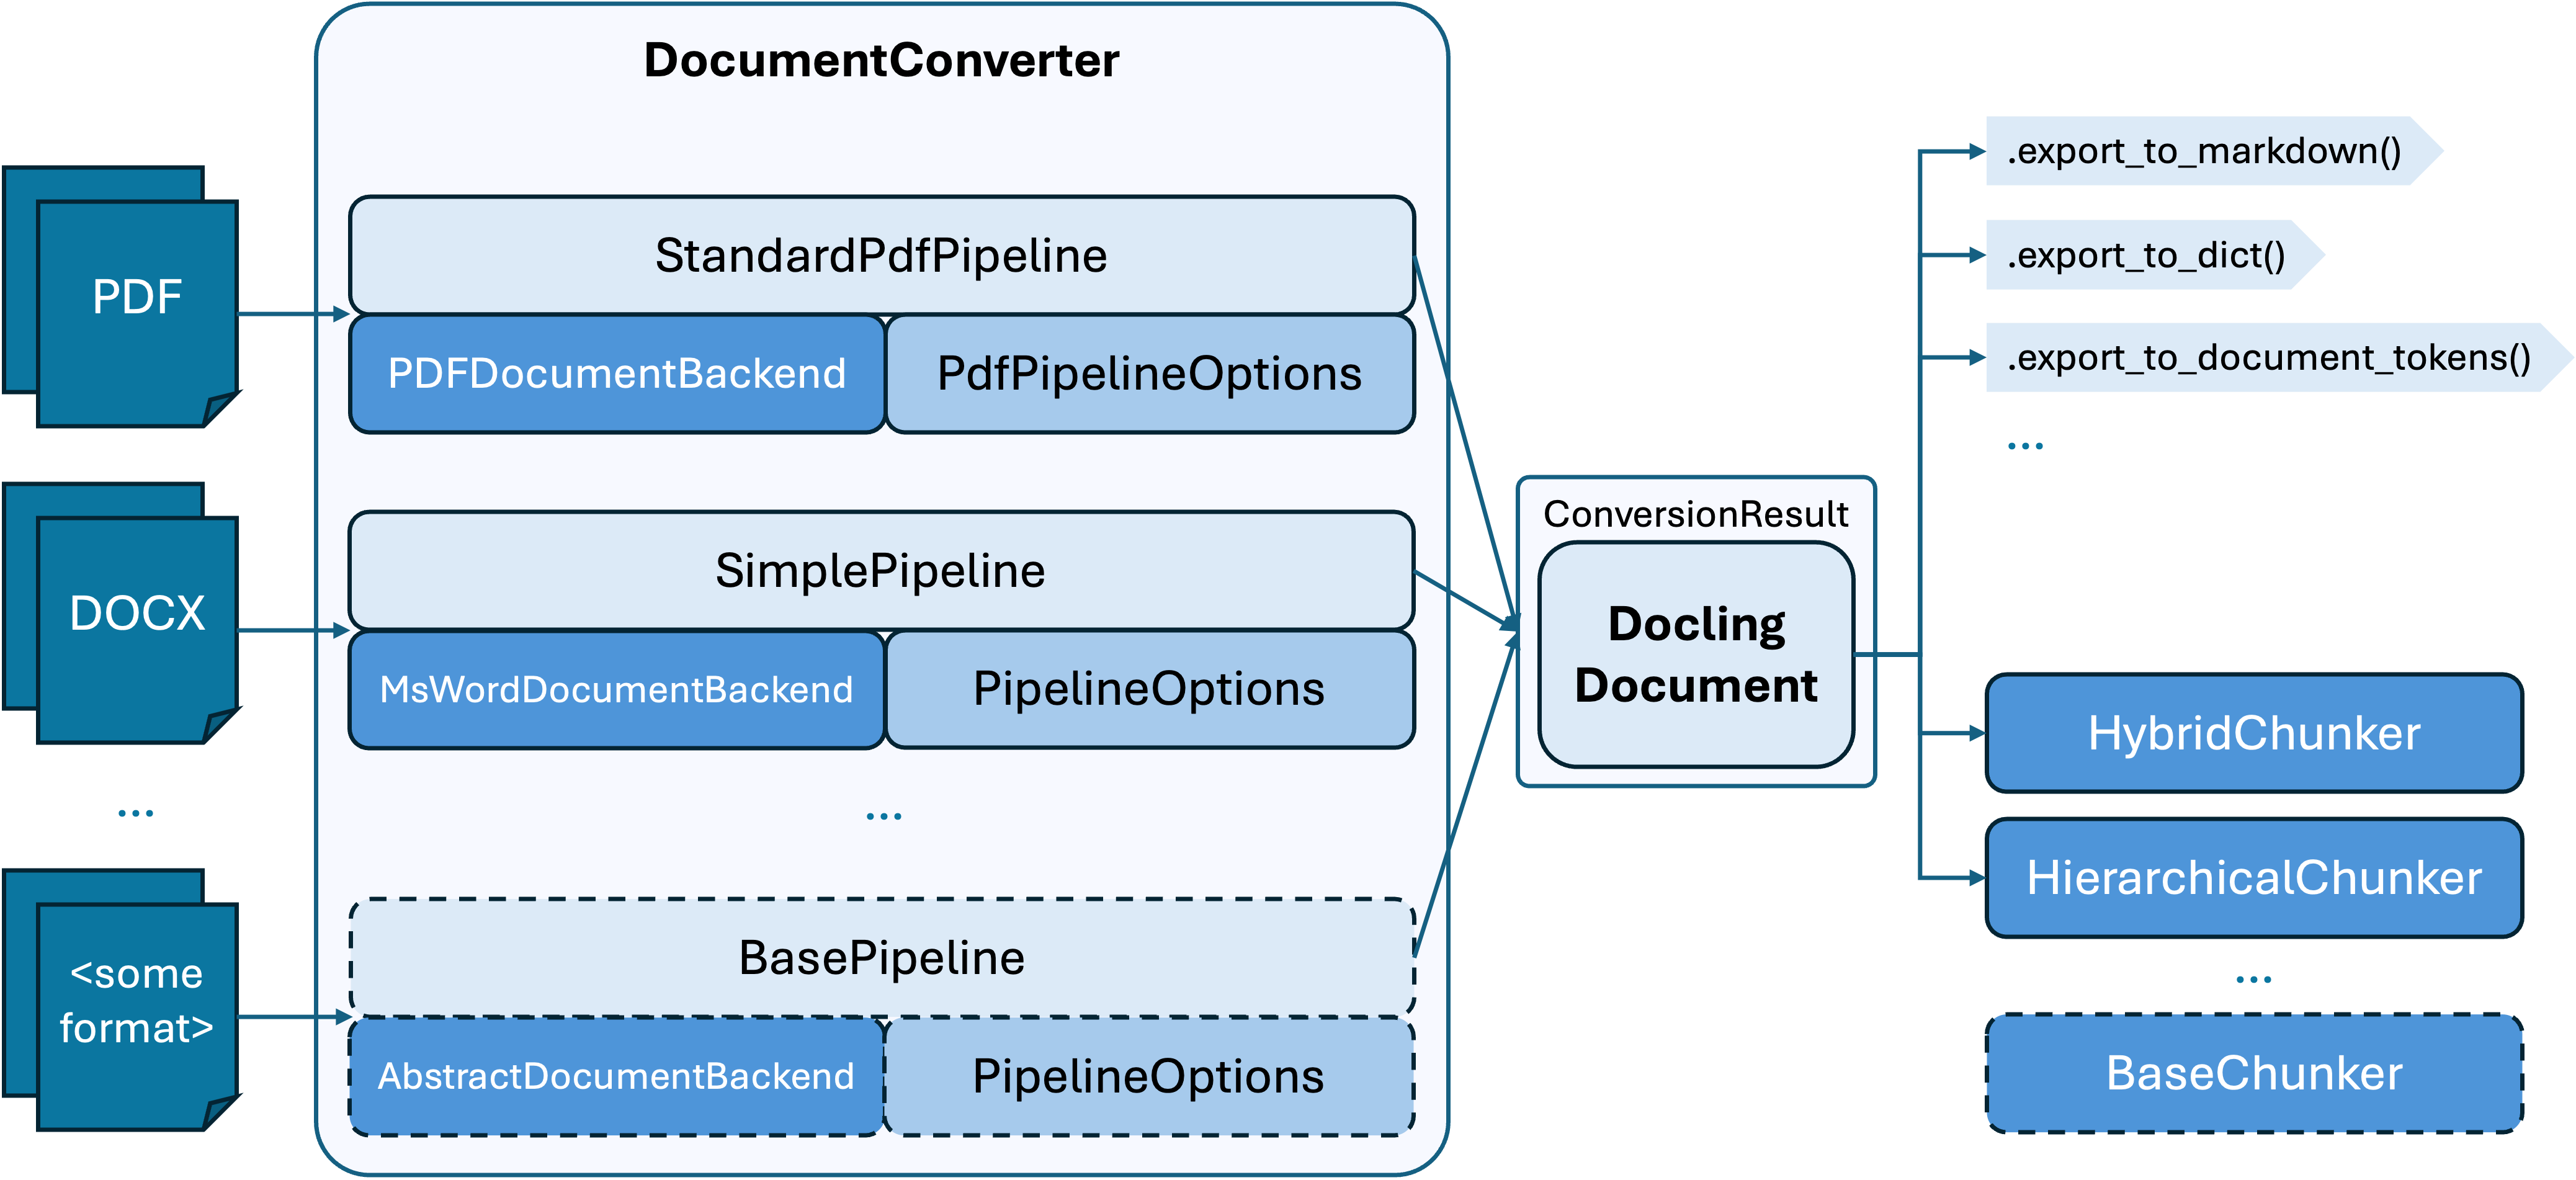
Docling is an open-source toolkit developed by IBM Research.
- Strengths: Runs locally with full data control, supports multiple formats (PDF, Word, PPT, HTML), high-quality output, free to use (MIT license), integrates with frameworks like LangChain and LlamaIndex.
- Weaknesses: Some gaps in handling formulas and charts, requires configuration, slower with large-scale document batches.
Docling is well-suited for organizations prioritizing data sovereignty and open-source flexibility.
MinerU – Research Tool with Formula Strengths
MinerU was developed in an academic context and focuses on scientific and technical use cases.
- Strengths: Automatic formula recognition with LaTeX output, strong table extraction, multilingual OCR (80+ languages), removes noise such as headers/footers.
- Weaknesses: Still early in development, higher compute requirements, lacks ready-made integrations with RAG frameworks.
MinerU is promising for research-heavy or technical domains, but still needs to mature for enterprise-scale use.
Conclusion: Mistral as the Best Choice for European Customers
All three tools improve LLM performance by transforming unstructured documents into structured Markdown. Open-source approaches like Docling and MinerU are compelling for organizations that demand full control and are willing to run their own infrastructure.
However, for those who need speed, scalability, and the highest recognition accuracy out of the box, Mistral OCR currently stands out as the best solution – particularly for European customers. It combines state-of-the-art performance with ease of integration, making unstructured data truly usable for LLM-driven applications.
Recources:
https://github.com/docling-project/docling
https://mistral.ai/news/mistral-ocr